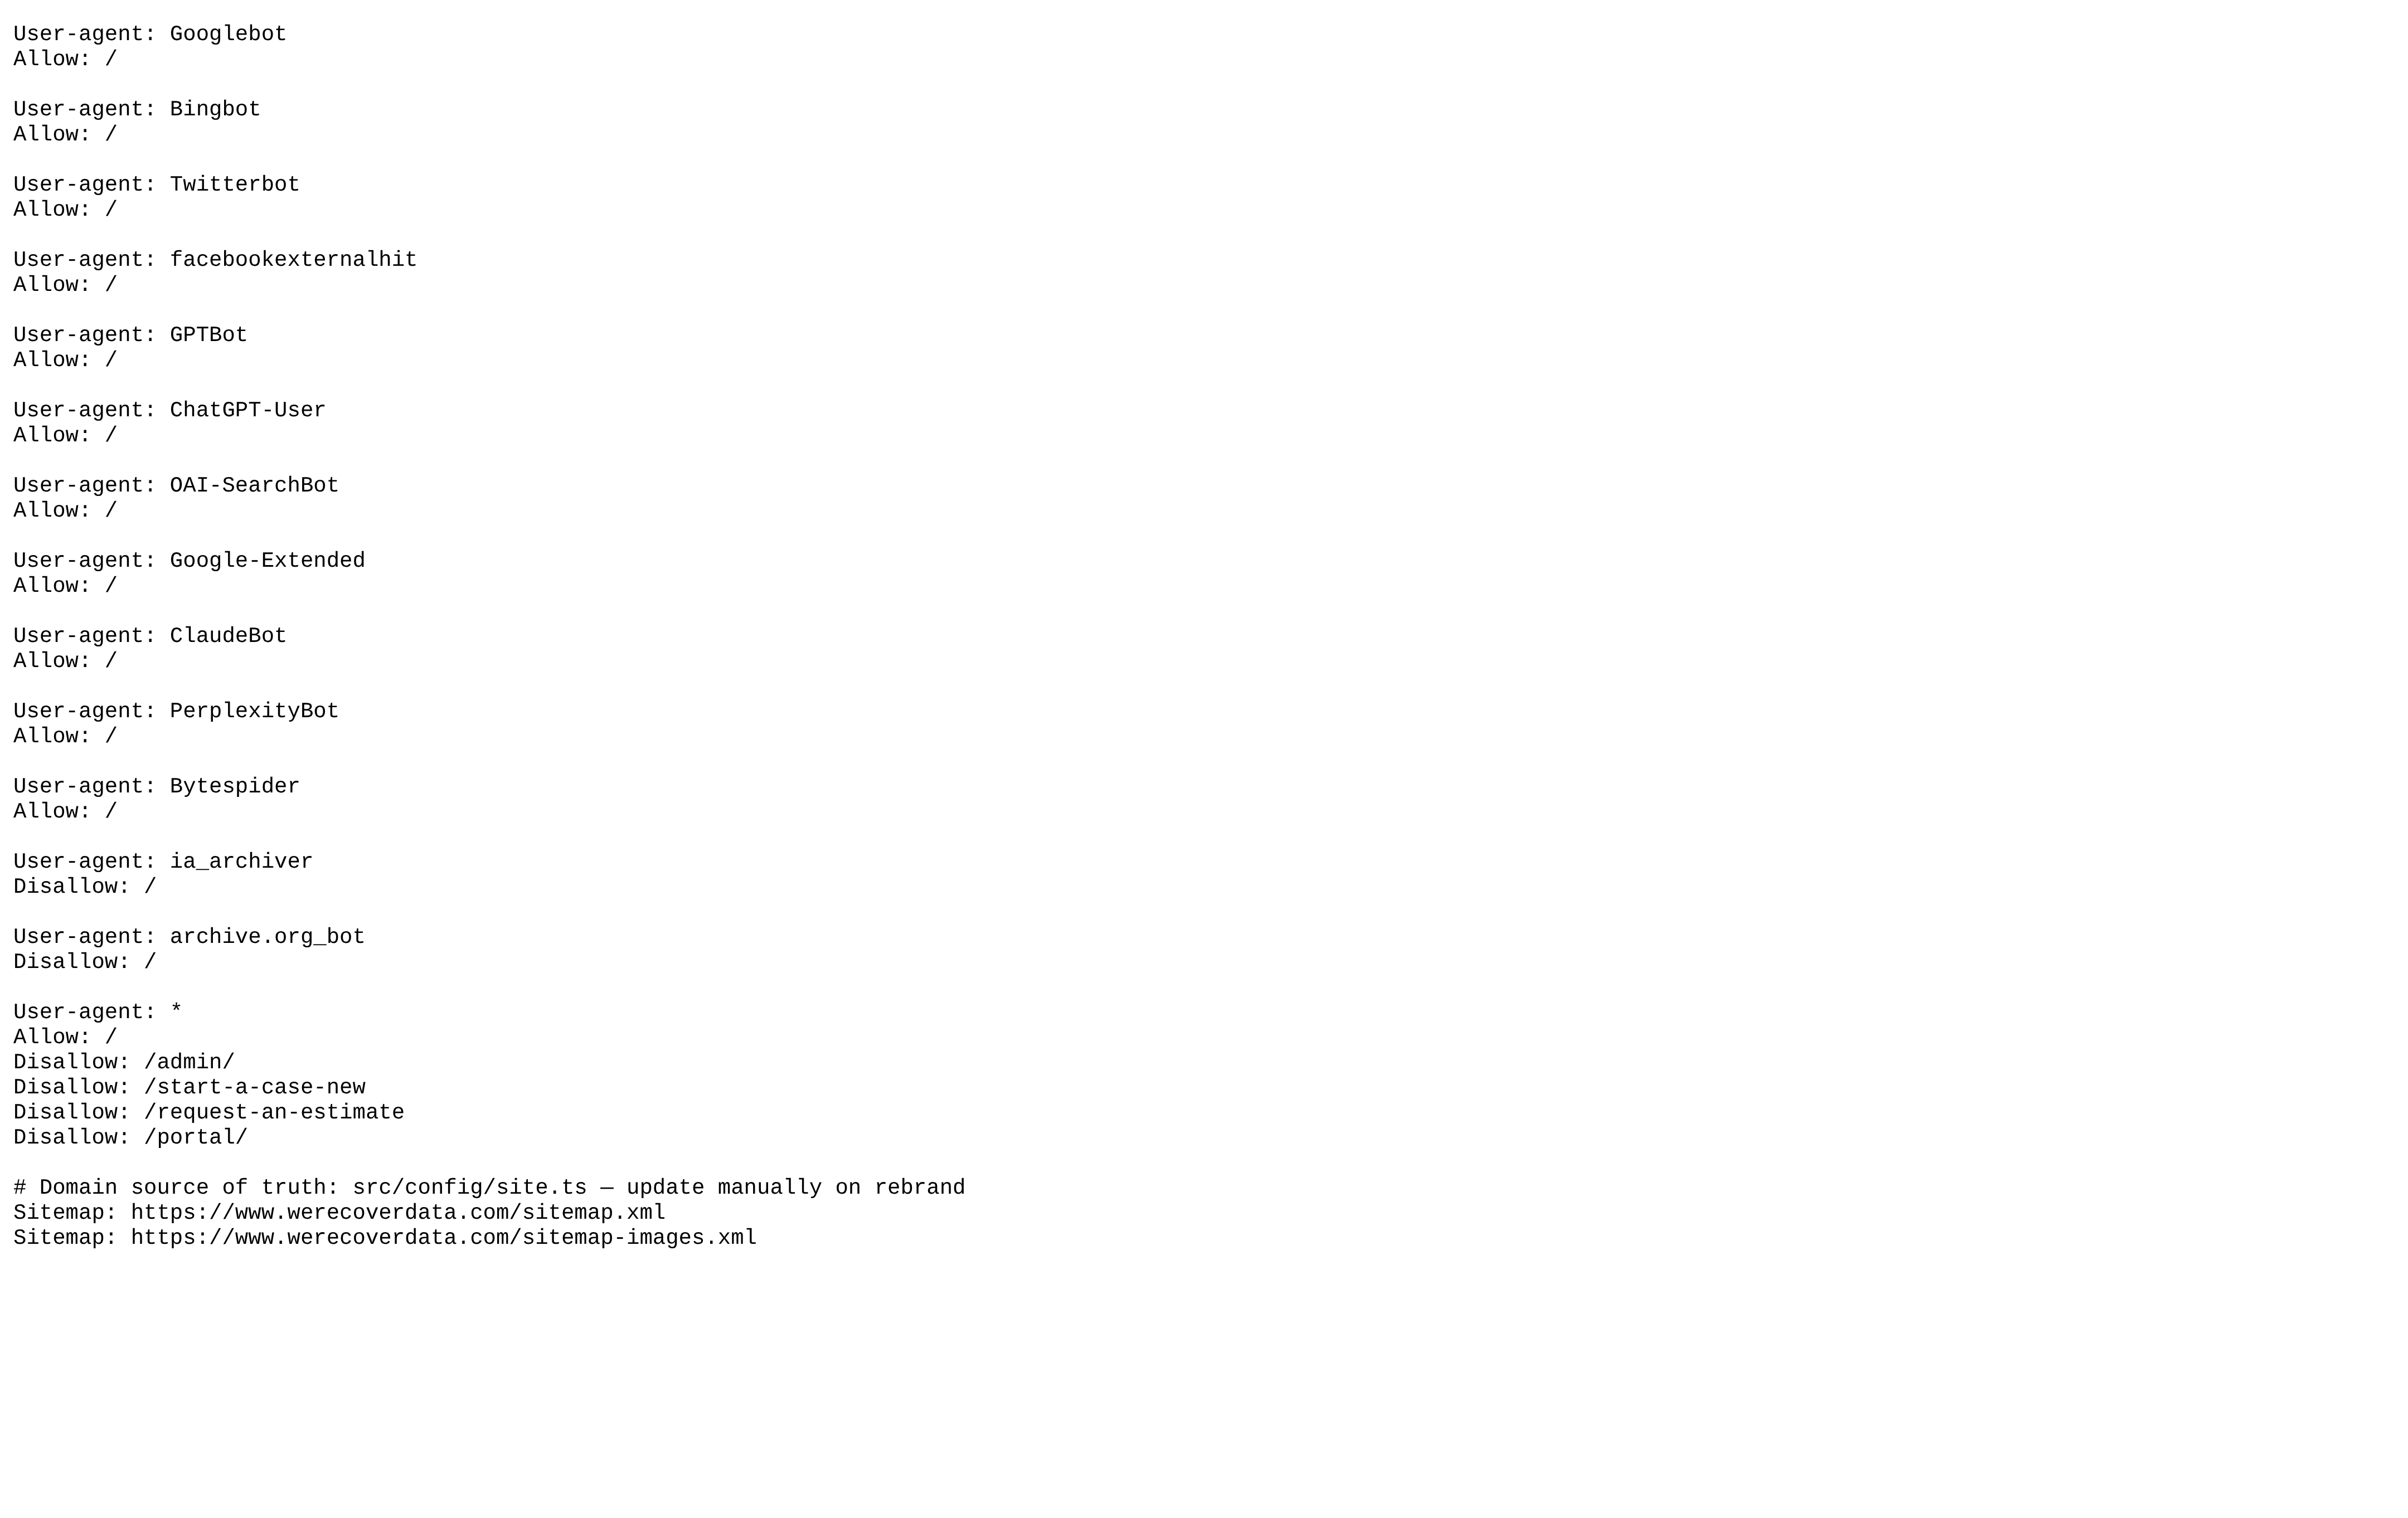
File:WeRecoverData-robots-txt-2026-07-13.png


Summary
[edit | edit source]

Screenshot of werecoverdata.com's robots.txt as served on July 13, 2026, showing that it allows mainstream and AI crawlers but disallows the Internet Archive's ia_archiver and archive.org_bot crawlers.
source: https://www.werecoverdata.com/robots.txt
Retrieved July 13, 2026
Licensing
[edit | edit source]


This file is a screenshot of the robots.txt file publicly served by werecoverdata.com at https://www.werecoverdata.com/robots.txt, captured as it existed on July 13, 2026. A robots.txt file consists of non-creative functional directives (user-agent, allow, and disallow lines) that tell automated crawlers which paths they may fetch. It is uploaded here by a person who retrieved the public file as documentation of the site's crawler directives at the time of capture. It is used on User:Louis/WeRecoverData's advertised US locations to show which crawlers werecoverdata.com allows and which it disallows, a limited factual purpose that does not substitute for any market for the work. Only the single robots.txt file is shown.
File history
Click on a date/time to view the file as it appeared at that time.
| Date/Time | Thumbnail | Dimensions | User | Comment | |
|---|---|---|---|---|---|
| current | 21:14, 13 July 2026 | | 4,320 × 2,724 (297 KB) | Louis (talk | contribs) | robots.txt of werecoverdata.com as served on july 13, 2026 |
You cannot overwrite this file.
File usage
The following page uses this file:
